A sweep answers a parameter question: which values of a declared set of knobs did what, on the same sealed evidence? This article turns such a question into candidate rows, inspects them, and promotes one candidate into a committed run you can reopen later. It assumes you have already written and run the strategy once; vignette("research-workflow", package = "ledgr") covers that loop and when a parameter question is the right next step.
Sweeps are for exploration. Promotion records one selected candidate as a committed run. Neither step proves that the selected candidate will generalize.
Prerequisites
This article uses dplyr for tabular inspection. The sweep itself is ledgr’s job.
Running this yourself
This article is evaluated when it is rendered, so it writes to a temporary store. In a real project, replace store_path with a durable path such as artifacts/ledgr_store.duckdb.
store_path <- ledgr_temp_store()Sweep Is Exploration
ledgr_sweep() evaluates a declared grid against a ledgr_experiment(). The result is an exploratory candidate table: it records what each candidate did, does not choose a winner, and does not write candidate runs to the experiment store.
Each candidate is one row of that table: resolved feature parameters, strategy parameters, execution seed, status, metrics, warnings or errors, and provenance.
That separation is the workflow boundary:
ledgr_sweep()                 explore declared candidates
ledgr_candidate()             select one row deliberately
ledgr_promote() / ledgr_run() commit an auditable run
Selection is not validation
A sweep table records what was run. It does not prove that the selected parameters were evaluated on held-out data. Promotion records a choice; it does not make that choice out-of-sample.
Declare Parameterized Features
Seal the evidence first. Here you use two demo instruments over the first half of 2019. Once the data is sealed, the snapshot becomes the identity of the evidence: every run below refers back to the same immutable input.
bars <- ledgr_demo_bars |>
  filter(
    instrument_id %in% c("DEMO_01", "DEMO_02"),
    between(ts_utc, ledgr_utc("2019-01-01"), ledgr_utc("2019-06-30"))
  )

snapshot <- ledgr_snapshot_from_df(
  bars,
  db_path = store_path,
  snapshot_id = "demo_2019_h1"
)

features <- ledgr_feature_map(
  fast = ledgr_ind_sma(ledgr_param("fast_n")),
  slow = ledgr_ind_sma(ledgr_param("slow_n"))
)

sma_crossover_strategy <- function(ctx, params) {
  targets <- ctx$flat()

  for (id in ctx$universe) {
    values <- ctx$features(id)
    if (
      ledgr_passed_warmup(values) &&
        ((values[["fast"]] / values[["slow"]]) - 1) > params$threshold
    ) {
      targets[id] <- params$qty
    }
  }

  targets
}

exp <- ledgr_experiment(
  snapshot = snapshot,
  strategy = sma_crossover_strategy,
  features = features,
  opening = ledgr_opening(cash = 10000),
  cost_model = ledgr_cost_zero()
)

exp
ledgr_experiment
================
Snapshot ID: demo_2019_h1
Database: <temporary DuckDB path>
Universe: 2 instruments
Features: 2 mapped
Opening: cash=10000, positions=0
Mode: audit_log
Price basis: <undeclared>
Metrics: US equity daily (default) (252 days/year * 1 bars/day = 252 bars/year)The strategy function itself does not change across candidates. At each pulse, ledgr calls the same function(ctx, params): ctx contains the current pulse-known market data, positions, cash, equity, and resolved alias values; params contains the strategy-parameter values for this candidate.
The function above is the strategy the experiment executes; it is not a separate illustrative approximation.
During a sweep, ctx$features(id) returns values for the concrete indicators resolved for that candidate. params$threshold and params$qty come from the strategy grid. For the full strategy contract, read vignette("strategy-development", package = "ledgr").
Read an active alias once across the decision axis with ctx$vec$feature("alias"). The same alias resolves to the concrete indicator owned by each candidate, so strategy code stays fixed while feature parameters vary. Use ctx$features(id) only when you deliberately need several mapped values for one instrument. There is no plural whole-universe accessor.
An active alias is a stable strategy-facing feature name whose concrete indicator can vary by candidate. The strategy can keep reading values[["fast"]] and values[["slow"]] even when one candidate uses SMA(5) and SMA(20) and another candidate uses SMA(10) and SMA(40). The alias is the strategy-facing contract. The concrete feature IDs and fingerprints are provenance.
Feature parameters vary the knobs exposed by a feature constructor. For ledgr_ind_sma(), the knob is n, the moving-average window. For TTR-backed features, the knobs are the supported arguments of the wrapped TTR indicator. You still need to understand the feature you are tuning; ledgr separates the parameter namespaces, but it does not decide which indicator arguments are economically meaningful.
Only knobs declared with ledgr_param("name") need values in the feature grid. Concrete arguments stay fixed. For example, ledgr_ind_sma(20) needs no feature_grid entry, while ledgr_ind_sma(ledgr_param("fast_n")) requires a scalar fast_n value for each candidate.
flowchart TB
  params["feature params<br/>fast_n = 5<br/>slow_n = 20"]
  indicators["concrete indicators<br/>SMA 5 and SMA 20"]
  aliases["stable aliases<br/>fast and slow"]
  strategy["strategy reads<br/>fast and slow"]

  params --> indicators --> aliases --> strategy
For a second candidate with fast_n = 10 and slow_n = 40, the same arrows resolve to SMA(10) and SMA(40), but the strategy still reads values[["fast"]] and values[["slow"]]. The aliases stay stable across candidates.
Build The Candidate Grid
Feature parameters materialize indicators before execution. Strategy parameters are passed to strategy(ctx, params) during execution. Keeping those namespaces separate is what lets a strategy read stable aliases while the sweep varies indicator windows. Use ledgr_feature_grid() for feature knobs, an ordinary data frame for strategy-code knobs, and ledgr_grid_cross() to combine them. ledgr_strategy_grid() remains available when its .filter syntax is useful.
For a strategy-only sweep, an ordinary data frame or tibble is enough: each row is one candidate and each column is one strategy parameter. Output from tidyr::crossing() has this same rectangular form and can be passed directly to ledgr_sweep(). Use the ledgr grid helpers below when feature parameters also vary, because that composition keeps feature and strategy names in distinct namespaces.
feature_grid <- ledgr_feature_grid(
  fast_n = c(5L, 10L),
  slow_n = c(20L, 40L),
  .filter = fast_n < slow_n
)

strategy_grid <- tibble::tibble(
  threshold = rep(c(0, 0.01), each = 2L),
  qty = rep(c(5, 10), times = 2L)
)

grid <- ledgr_grid_cross(features = feature_grid, strategy = strategy_grid)
grid
ledgr_executable_grid
=====================
Candidates: 16
Labels: feature_9a29b31dae19/strategy_86be010cf688, feature_9a29b31dae19/strategy_ab759ad88623, feature_9a29b31dae19/strategy_7ccbbefd14d1, feature_9a29b31dae19/strategy_dc6315936028, feature_af0f94c90243/strategy_86be010cf688, feature_af0f94c90243/strategy_ab759ad88623
... 10 moreThe .filter expression is a structural grid constraint. Here it says the fast moving average must be shorter than the slow moving average. Filter expressions are evaluated against grid columns; they do not read run state, feature data, or caller globals.
Mind the combinatorial explosion
ledgr_grid_cross() multiplies grid dimensions. Four parameters with five values each produce 625 candidates before you add another axis. Keep early sweeps deliberately small, then expand only after the candidate table is readable and the feature payload cost is understood.
The cross product is explicit:
flowchart TB
  fg["feature_grid<br/>fast_n, slow_n"]
  sg["strategy_grid<br/>threshold, qty"]
  cross["grid_cross"]
  rows["candidate rows<br/>feature params + strategy params"]

  fg --> cross
  sg --> cross
  cross --> rows
Try it
Run this larger grid. The strategy code and its fast and slow aliases do not change; only the concrete feature parameters do.
expanded_grid <- ledgr_grid_cross(
  features = ledgr_feature_grid(
    fast_n = c(5L, 10L),
    slow_n = c(20L, 40L, 60L),
    .filter = fast_n < slow_n
  ),
  strategy = strategy_grid
)

tibble(
  grid_name = c("original", "expanded"),
  candidates = c(length(grid$params), length(expanded_grid$params)),
  feature_combinations = c(
    nrow(distinct(bind_rows(lapply(grid$params, `[[`, "feature_params")))),
    nrow(distinct(bind_rows(lapply(
      expanded_grid$params,
      `[[`,
      "feature_params"
    ))))
  )
)
# A tibble: 2 x 3
grid_name candidates feature_combinations
<chr> <int> <int>
1 original 16 4
2 expanded 24 6Precompute Shared Features
Precomputing is an execution optimization, not a separate research decision. The same declared feature grid is resolved once, deduplicated by fingerprint, and reused across sweep candidates.
precomputed <- ledgr_precompute_features(exp, grid)
precomputed
ledgr_precomputed_features
===========================
Snapshot: demo_2019_h1
Candidates: 16
Features: 4
Universe: DEMO_01, DEMO_02
Scoring: 2019-01-01T00:00:00Z to 2019-06-28T00:00:00Zledgr_sweep() can compute features internally for small grids. For larger grids, precompute first so feature resolution and payload validation are explicit. When a grid has more than 20 combinations and no precomputed payload, ledgr warns because feature computation may be repeated per candidate.
Run The Sweep
Give the sweep a master seed when reproducible stochastic strategy behavior matters. Each row receives its own derived execution_seed. The default sweep is scalar-only: it keeps candidate summary rows but not per-pulse return series.
sweep <- ledgr_sweep(
  exp,
  grid,
  precomputed_features = precomputed,
  seed = 2026L
)

sweep
# ledgr sweep -- sweep_5ad676747ad4372a
# A tibble: 16 x 10
strategy_params feature_params candidate_id candidate_row status sharpe_ratio
<chr> <chr> <chr> <int> <chr> <dbl>
1 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_9a2~ 1 DONE 0.546
2 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_9a2~ 2 DONE 0.551
3 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_9a2~ 3 DONE 3.08
4 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_9a2~ 4 DONE 3.08
5 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_af0~ 5 DONE 1.80
6 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_af0~ 6 DONE 1.81
7 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_af0~ 7 DONE 2.06
8 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_af0~ 8 DONE 2.06
9 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_6ff~ 9 DONE 1.38
10 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_6ff~ 10 DONE 1.39
11 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_6ff~ 11 DONE 2.13
12 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_6ff~ 12 DONE 2.13
13 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_fa5~ 13 DONE 1.34
14 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_fa5~ 14 DONE 1.35
15 "{\"qty\":5.0,\"threshol~ "{\"fast_n\":~ feature_fa5~ 15 DONE 1.30
16 "{\"qty\":10.0,\"thresho~ "{\"fast_n\":~ feature_fa5~ 16 DONE 1.31
# i 4 more variables: total_return <chr>, max_drawdown <chr>, n_trades <int>,
# execution_seed <int>
# i 16 candidates attempted: 16 done, 0 incomplete, 0 failed.
# i Retention returns: none.
# i Retention trades: none.
# i Snapshot hash: 1f315cc620d0849849114d32cb44b042ec567f9512db99ad802c4ac89efe3a43.
# i Cost model hash: 4011132b5979fc370e524ebbc525ac7f4158b4de43639ec985f4c90969b4b9d0.
# i Metric context hash: 794b69bd7f9c704447d4b0208b8420cdf132ec7bd6582eaa037bf1066133c1bb.
# i Saved artifact: not saved.
# i Rows are printed in their current table order; rank or arrange explicitly before selecting candidates.
# i Hidden columns (24): completion_json, stop_reason, affected_instrument_ids, valuation_state, frozen_instrument_sessions, max_frozen_equity_weight, frozen_at_end_value, assumed_terminal_outcomes, final_equity, annualized_return, volatility, win_rate, avg_trade, time_in_market, error_class, error_msg, params, warnings, feature_fingerprints, risk_chain_hash, provenance, t_engine, t_results, t_fills_extract# A tibble: 16 x 6
candidate_id status threshold qty fast_n slow_n
<chr> <chr> <dbl> <dbl> <int> <int>
1 feature_9a29b31dae19/strategy_86be010cf688 DONE 0 5 5 20
2 feature_9a29b31dae19/strategy_ab759ad88623 DONE 0 10 5 20
3 feature_9a29b31dae19/strategy_7ccbbefd14d1 DONE 0.01 5 5 20
4 feature_9a29b31dae19/strategy_dc6315936028 DONE 0.01 10 5 20
5 feature_af0f94c90243/strategy_86be010cf688 DONE 0 5 10 20
6 feature_af0f94c90243/strategy_ab759ad88623 DONE 0 10 10 20
7 feature_af0f94c90243/strategy_7ccbbefd14d1 DONE 0.01 5 10 20
8 feature_af0f94c90243/strategy_dc6315936028 DONE 0.01 10 10 20
9 feature_6ff6fe3a1d38/strategy_86be010cf688 DONE 0 5 5 40
10 feature_6ff6fe3a1d38/strategy_ab759ad88623 DONE 0 10 5 40
11 feature_6ff6fe3a1d38/strategy_7ccbbefd14d1 DONE 0.01 5 5 40
12 feature_6ff6fe3a1d38/strategy_dc6315936028 DONE 0.01 10 5 40
13 feature_fa560ccbec9f/strategy_86be010cf688 DONE 0 5 10 40
14 feature_fa560ccbec9f/strategy_ab759ad88623 DONE 0 10 10 40
15 feature_fa560ccbec9f/strategy_7ccbbefd14d1 DONE 0.01 5 10 40
16 feature_fa560ccbec9f/strategy_dc6315936028 DONE 0.01 10 10 40The second view connects each status row to the strategy and feature parameters that produced it. The table is not a full artifact store and it does not write durable candidate ledgers, equity curves, feature panels, or telemetry rows. Each row keeps the compact reproduction key needed for later materialization: snapshot identity, selector, strategy identity, feature fingerprints, seed metadata, and candidate params. Use ledgr_candidate_reproduction_key() when you want to inspect that key directly. Full equity, fills, trades, and ledger rows are created only by committed runs.
ledgr_sweep() is the memory-backed exploration mode. It evaluates candidate rows with the same execution rules as committed runs, but it keeps compact candidate evidence instead of writing a durable ledger and equity curve for every row. Promotion is the point where one selected candidate pays the durable-materialization cost.
If the experiment declares a risk_chain, sweep candidates also carry risk_chain_hash and row-level provenance carries risk_plan_json. These fields are execution identity: they say which target-risk plan transformed the validated strategy targets before fill timing and cost resolution. They do not rank candidates, select winners, estimate liquidity, enforce broker policy, or turn risk settings into a separate grid-composition surface. Parameterized risk arguments use ordinary candidate params through ledgr_param().
Retain Candidate Return Series
When you need per-pulse net portfolio equity or adjacent-period returns for completed candidates, opt in explicitly with ledgr_sweep_retention().
retained_sweep <- ledgr_sweep(
  exp,
  grid,
  precomputed_features = precomputed,
  seed = 2026L,
  retain = ledgr_sweep_retention("completed")
)

retained_long <- ledgr_sweep_returns(retained_sweep)

retained_long |>
  select(sweep_id, candidate_id, ts_utc, equity, period_return) |>
  slice_head(n = 8)
# A tibble: 8 x 5
sweep_id candidate_id ts_utc equity period_return
<chr> <chr> <dttm> <dbl> <dbl>
1 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-01 00:00:00 10000 NA
2 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-02 00:00:00 10000 0
3 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-03 00:00:00 10000 0
4 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-04 00:00:00 10000 0
5 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-07 00:00:00 10000 0
6 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-08 00:00:00 10000 0
7 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-09 00:00:00 10000 0
8 sweep_102aeed66d616d00 feature_9a29b31dae19/st~ 2019-01-10 00:00:00 10000 0Each candidate_id here is a row of candidate_table above, which lists the parameters that produced it.
period_return is NA_real_ on the first retained row for each candidate because there is no prior equity value to compare against. Drop that first return before handing the series to an external metric package:
external_metric_input <- retained_long |>
  filter(!is.na(period_return)) |>
  select(ts_utc, candidate_id, period_return)

external_metric_input |>
  slice_head(n = 8)
# A tibble: 8 x 3
ts_utc candidate_id period_return
<dttm> <chr> <dbl>
1 2019-01-02 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0
2 2019-01-03 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0
3 2019-01-04 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0
4 2019-01-07 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0
5 2019-01-08 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0
6 2019-01-09 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0
7 2019-01-10 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0
8 2019-01-11 00:00:00 feature_9a29b31dae19/strategy_86be010cf688 0The retained series are net strategy returns. They include the execution costs resolved by the experiment’s cost model, but they are not benchmark-relative returns and they do not contain gross-vs-net attribution. Failed candidates remain in the sweep summary table but have no retained return rows.
Final-bar no-fill warnings are row-level warnings on the candidate summary. They do not remove the final equity row from retained return series.
Use the wide accessor when a downstream tool expects one return or equity column per candidate:
ledgr_sweep_returns_wide(
  retained_sweep,
  candidates = retained_sweep$candidate_id[1:3],
  value = "returns"
) |>
  slice_head(n = 5)
# A tibble: 5 x 4
ts_utc feature_9a29b31dae19~1 feature_9a29b31dae19~2 feature_9a29b31dae19~3
<dttm> <dbl> <dbl> <dbl>
1 2019-01-01 00:00:00 NA NA NA
2 2019-01-02 00:00:00 0 0 0
3 2019-01-03 00:00:00 0 0 0
4 2019-01-04 00:00:00 0 0 0
5 2019-01-07 00:00:00 0 0 0
# i abbreviated names: 1: `feature_9a29b31dae19/strategy_86be010cf688`,
# 2: `feature_9a29b31dae19/strategy_ab759ad88623`,
# 3: `feature_9a29b31dae19/strategy_7ccbbefd14d1`Save And Reopen Sweep Artifacts
A saved sweep is a compact artifact. It stores candidate summary evidence and, when requested, retained net equity/return series. It is not a batch of committed runs: full ledgers, fills, trades, and per-instrument artifacts remain available only after explicit promotion.
saved_id <- ledgr_sweep_save(
  retained_sweep,
  snapshot,
  sweep_id = "sma_retained_sweep",
  note = "Exploratory SMA sweep with retained return series."
)

ledgr_sweep_list(snapshot)
# ledgr saved sweep list
# A tibble: 1 x 8
sweep_id created_at_utc sweep_schema_version n_candidates n_completed
<chr> <dttm> <int> <int> <int>
1 sma_retained_sweep 2026-10-27 17:47:57 6 16 16
# i 3 more variables: retention_returns <chr>, retention_trades <chr>, note <chr>
# i Open one saved sweep with ledgr_sweep_open(snapshot, sweep_id).
reopened_sweep <- ledgr_sweep_open(snapshot, saved_id)

ledgr_sweep_info(reopened_sweep)
ledgr Sweep Info
================
Sweep ID: sma_retained_sweep
Snapshot: demo_2019_h1
Snapshot Hash: 1f315cc620d0849849114d32cb44b042ec567f9512db99ad802c4ac89efe3a43
Candidates: 16
Completed: 16
Failed: 0
Retention returns: completed
Retention trades: none
Cost Model Hash: 4011132b5979fc370e524ebbc525ac7f4158b4de43639ec985f4c90969b4b9d0
Metric Hash: 794b69bd7f9c704447d4b0208b8420cdf132ec7bd6582eaa037bf1066133c1bb
Feature Union: 8dcc07d45aaa9cfcc74ef1d6cd33e51cae4af2cc1c06b345152c443ae5c303dc
Saved artifact
Created At: 2026-10-27 17:47:57.21978
Schema Version: 6
Engine Version: 0.2.2
Note: Exploratory SMA sweep with retained return series.Reopened sweeps behave like sweep result objects for candidate extraction, ordinary dplyr inspection, retained return access, and promotion. Promotion from a reopened saved sweep re-executes the selected candidate from its reproduction key against the sealed snapshot; it does not replay precomputed retained return rows as if they were a committed ledger.
ledgr_sweep_returns(reopened_sweep) |>
  filter(candidate_id == reopened_sweep$candidate_id[[1]]) |>
  slice_head(n = 5)
# A tibble: 5 x 6
sweep_id candidate_id status ts_utc equity period_return
<chr> <chr> <chr> <dttm> <dbl> <dbl>
1 sma_retained_sweep feature_9a29b31dae19~ DONE 2019-01-01 00:00:00 10000 NA
2 sma_retained_sweep feature_9a29b31dae19~ DONE 2019-01-02 00:00:00 10000 0
3 sma_retained_sweep feature_9a29b31dae19~ DONE 2019-01-03 00:00:00 10000 0
4 sma_retained_sweep feature_9a29b31dae19~ DONE 2019-01-04 00:00:00 10000 0
5 sma_retained_sweep feature_9a29b31dae19~ DONE 2019-01-07 00:00:00 10000 0Three Retention Levels
Sweeps give you three retention levels. Use the cheapest level that answers the question in front of you, then promote only the candidate that needs committed-run artifacts.
| Level | What it keeps | Typical use |
|---|---|---|
| Scalar row | Candidate params, status, scalar metrics, warnings, and reproduction key | Screen and debug a declared grid |
| Retained series | Scalar row plus net portfolio equity and period returns for completed candidates | Inspect return shape, rolling behavior, or external metric-package inputs |
| Promoted run | Full committed run artifacts: ledger, fills, trades, equity, metrics, and promotion context | Audit and reopen the selected candidate as a durable run |
Retention does not change execution identity. It changes which derived evidence is kept after the same candidate execution.
Saved sweeps persist the same risk identity fields on the parent sweep row and candidate rows. They reopen only from the current experiment-store and saved-sweep formats; ledgr does not migrate an older research store in place.
What Retained Returns Can And Cannot Validate
Retained returns make triage better because they let you inspect the path of a candidate, not just its final scalar score. They can help you notice unstable return profiles, drawdown concentration, missing warmup behavior, and candidates whose scalar score hides a bad path.
They do not make the sweep statistically valid. If you selected the candidate from the same sample, the retained path is still in-sample evidence. Generalized validation belongs to a held-out evaluation, walk-forward analysis, or the selection-integrity diagnostics taught in vignette("selection-integrity", package = "ledgr").
Return paths are not validation by themselves
Retained series preserve more evidence from a sweep. They do not prove that the candidate-selection process was sound.
Why ledgr And PerformanceAnalytics Metrics May Differ
Retained return series can be shaped for packages such as PerformanceAnalytics, but ledgr metrics and external package metrics may differ. Annualization, calendar assumptions, treatment of the leading missing return, and return-shape conventions are package contracts, not universal truths.
Keep ledgr’s scalar metric rows as the canonical ledgr evidence. Use external metric packages as additional analysis over an explicit return series, and label any overlapping headline metric when it comes from a different convention.
Compiled Accounting And Workers
The default sweep path is memory-backed and uses ledgr’s standard R accounting. When your workload is spot-asset FIFO and you want the scoped compiled accelerator, opt in explicitly:
fifo_sweep <- ledgr_sweep(
  exp,
  grid,
  precomputed_features = precomputed,
  seed = 2026L,
  compiled_accounting_model = "spot_fifo"
)

identical(fifo_sweep$final_equity, sweep$final_equity)
[1] TRUEThe compiled path changes how the accounting is computed, not the result: every candidate ends with the same final equity as in the canonical sweep above.
compiled_accounting_model = NULL remains the default. "spot_fifo" is a memory-backed sweep accelerator only: it is not a general compiled execution engine, not the durable ledgr_run() path, not a non-spot accounting model, and not enabled by default. A committed ledgr_run() that requests it stops with an error. Unsupported model names raise ledgr_unsupported_accounting_model, and missing compiled support raises ledgr_compiled_spot_fifo_unavailable.
For independent candidates, workers can dispatch sweep rows in parallel when the required backend and worker package dependencies are available. Parallelism changes candidate dispatch, not strategy semantics; interrupted parallel sweeps discard the partial table instead of returning partially promotable rows. That means parallel sweep execution is a dispatch choice over independent candidate rows, not a second execution engine.
Workers are not memory-free. Each process receives prepared run state, so peak memory rises with the worker count. The retained v0.2.2 long-window record peaked at 1.89 GiB for one H1 run and 4.46 GiB for the two-worker tree. Treat those as workload-specific sizing evidence, not a universal estimate, and use workers = 1L when memory is the tighter constraint.
Failure Rows And Contract Errors
By default, candidate-level failures become rows with status = "FAILED". Inspect those rows before selecting anything.
This debug example uses no features so the failure is only about strategy parameters. In ordinary research, the experiment usually declares features just like the main sweep above.
debug_strategy <- function(ctx, params) {
  if (params$qty < 0) {
    stop("qty must be non-negative")
  }
  ctx$flat()
}

debug_exp <- ledgr_experiment(
  snapshot = snapshot,
  strategy = debug_strategy,
  features = list(),
  opening = ledgr_opening(cash = 10000),
  cost_model = ledgr_cost_zero()
)

debug_grid <- ledgr_strategy_grid(qty = c(5, -1))

failed_sweep <- ledgr_sweep(debug_exp, debug_grid)

failed_sweep |>
  mutate(qty = vapply(params, function(p) p$qty, numeric(1))) |>
  select(candidate_id, qty, status, error_class, error_msg)
# A tibble: 2 x 5
candidate_id qty status error_class error_msg
<chr> <dbl> <chr> <chr> <chr>
1 strategy_69e7ad01d1e8 5 DONE <NA> <NA>
2 strategy_8d5f90d900e7 -1 FAILED ledgr_strategy_error "Strategy error at ts_utc=2019-~Use the failed row as an interactive debugging handle: inspect error_class, error_msg, and params, then reproduce the single candidate in a smaller session before rerunning the sweep. For pulse-level strategy debugging patterns, read vignette("strategy-development", package = "ledgr").
Contract errors still abort before a candidate table exists. Invalid experiment or grid shape is not a failed strategy idea; it is a setup problem that ledgr stops immediately so the sweep does not mix incomparable rows.
ledgr_candidate() rejects failed rows by default. Use ledgr_candidate(results, which, allow_failed = TRUE) only when you are extracting a failed row for diagnostics; ledgr_promote() still rejects failed candidates.
Inspect Before Promotion
Name the ranking rule before selecting. Here the rule is deliberately simple: among completed candidates, sort by Sharpe ratio descending. ledgr ships business-objective helpers for explicit selection rules, as taught in vignette("selection-integrity", package = "ledgr"); it does not silently choose a winner. This example keeps the rule visible as ordinary R code, and it reads the reopened saved sweep to show that a saved sweep reopens to the same dplyr-friendly surface as the in-session result.
# A tibble: 5 x 6
  candidate_id                               sharpe_ratio threshold   qty fast_n slow_n
  <chr>                                             <dbl>     <dbl> <dbl>  <int>  <int>
1 feature_9a29b31dae19/strategy_dc6315936028         3.08      0.01    10      5     20
2 feature_9a29b31dae19/strategy_7ccbbefd14d1         3.08      0.01     5      5     20
3 feature_6ff6fe3a1d38/strategy_dc6315936028         2.13      0.01    10      5     40
4 feature_6ff6fe3a1d38/strategy_7ccbbefd14d1         2.13      0.01     5      5     40
5 feature_af0f94c90243/strategy_dc6315936028         2.06      0.01    10     10     20
review$issues# A tibble: 0 x 10
# i 10 variables: strategy_params <chr>, feature_params <chr>, candidate_id <chr>,
# candidate_row <int>, status <chr>, stop_reason <chr>, affected_instrument_ids <list>,
# error_class <chr>, error_msg <chr>, warnings <list>
ranked <- review$rankedThe join to candidate_table shows what each top candidate is. The top rows come in pairs that differ only in qty: doubling the quantity doubles the profit but leaves the Sharpe ratio unchanged, so this ranking cannot tell them apart. A rule that must choose between them needs a second criterion.
ledgr_sweep_review() packages the inspection shape while keeping the ranking rule explicit in the call. review$top is for the candidates you want to read closely, review$issues is for warnings and failures, and review$ranked retains the full completed-candidate table for deliberate selection.
Try it
Sort by total_return instead of sharpe_ratio. Does the first candidate change? If it does, your “best” candidate depends on the metric, not only on the strategy.
Promote One Candidate With A Note
Promotion replays one selected candidate as a committed run and attaches the human selection note. This is the slow path that explicitly pays to materialize durable ledger and equity artifacts.
candidate <- ledgr_candidate(ranked, 1)

candidate_table |>
  filter(candidate_id == candidate$candidate_id)
# A tibble: 1 x 6
candidate_id status threshold qty fast_n slow_n
<chr> <chr> <dbl> <dbl> <int> <int>
1 feature_9a29b31dae19/strategy_dc6315936028 DONE 0.01 10 5 20
promoted_run <- ledgr_promote(
  exp,
  candidate,
  run_id = "workflow_promoted_candidate",
  note = paste(
    "Promoted from an exploratory same-snapshot sweep for workflow review.",
    "This note records the selection rationale; it is not statistical validation."
  )
)

summary(promoted_run)
ledgr Backtest Summary
======================
Performance Metrics:
Total Return: 2.25%
Annualized Return: 4.48%
Max Drawdown: -0.64%
Risk Metrics:
Risk-Free Rate: 0.00% annual
Annualization: 252 periods/year (US equity daily (default))
Volatility (annual): 1.42%
Sharpe Ratio: 3.084
Trade Statistics:
Closed Trades: 3
Win Rate: 100.00%
Avg Trade: $75.05
Exposure:
Time in Market: 63.57%
Execution Evidence:
Fill Timing: dense_bar_timestamp
Corporate-Action Evidence:
Economic events: NOT SUPPLIED - returns may omit distributions
Price basis: UNDECLARED - distribution double counting cannot be ruled out
Full policy record: ledgr_corporate_action_summary(bt)Three closed trades on two instruments over half a year are far too few to judge a rule: the 100% win rate and the Sharpe ratio above describe this small sample, not the strategy. The promoted run is now a committed run with its own run ID. The selection note travels with the run. Same-snapshot promotion is useful for audit, debugging, and durable storage of the chosen candidate. It remains in-sample.
Reopen The Promoted Run
The payoff for the project store is that you can come back later without re-running the strategy. Release the live handles, reopen the snapshot with hash verification, and open the promoted run by its ID.
close(promoted_run)
ledgr_snapshot_close(snapshot)

snapshot <- ledgr_snapshot_open(
  store_path,
  snapshot_id = "demo_2019_h1",
  verify = TRUE
)

ledgr_run_list(snapshot)
# ledgr run list
# A tibble: 1 x 11
run_id label tags status final_equity total_return
<chr> <chr> <chr> <chr> <dbl> <chr>
1 workflow_promoted_candidate <NA> <NA> DONE 10225. +2.3%
complete_performance achieved_end_utc valuation_state execution_mode
<lgl> <dttm> <chr> <chr>
1 NA NA <NA> audit_log
reproducibility_level
<chr>
1 tier_1
# i 1 runs attempted: 1 done, 0 incomplete, 0 failed.
# i INCOMPLETE metrics describe the achieved prefix only.
# i Full identity and telemetry columns remain available on this tibble.
# i Inspect one run with ledgr_run_info(snapshot, run_id).
reopened <- ledgr_run_open(snapshot, "workflow_promoted_candidate")
reopened
ledgr Backtest Results
======================
Run ID: workflow_promoted_candidate
Period: 2019-01-01 to 2019-06-28
Opening Cash: $10000.00
Final Equity: $10225.14
Total Return: 2.25%
Max Drawdown: -0.64%
Closed Trades: 3
Metric Calendar: US equity daily (default) (252 days/year * 1 bars/day = 252 bars/year)
Economic events: NOT SUPPLIED - returns may omit distributions
Price basis: UNDECLARED - distribution double counting cannot be ruled out
Use summary(bt) for metrics and evidenceThree public readers recover what ledgr recorded about the promoted run:
-
ledgr_run_info()for the run’s identity and completion evidence; -
ledgr_promotion_context()for the selected sweep row, its parameters and the promotion note; -
ledgr_run_strategy()for strategy source and parameter provenance.
promotion <- ledgr_promotion_context(reopened)
list(
  source = promotion$source,
  selected_candidate = promotion$selected_candidate$candidate_id,
  selected_candidate_row = promotion$selected_candidate$candidate_row,
  strategy_params_json = promotion$selected_candidate$params_json,
  feature_params_json = promotion$selected_candidate$feature_params_json,
  note = promotion$note
)
$source
[1] "ledgr_promote"
$selected_candidate
[1] "feature_9a29b31dae19/strategy_dc6315936028"
$selected_candidate_row
[1] 4
$strategy_params_json
[1] "{\"qty\":10.0,\"threshold\":0.01}"
$feature_params_json
[1] "{\"fast_n\":5,\"slow_n\":20}"
$note
[1] "Promoted from an exploratory same-snapshot sweep for workflow review. This note records the selection rationale; it is not statistical validation."
extracted <- ledgr_run_strategy(
  snapshot,
  "workflow_promoted_candidate",
  trust = FALSE
)

extracted$strategy_params
$qty
[1] 10
$threshold
[1] 0.01
extracted$reproducibility_level[1] "tier_1"
extracted$hash_verified[1] TRUEThe result is compact but load-bearing: ledgr stores which sweep candidate was selected, which strategy parameters and feature parameters produced it, what note justified the promotion, and which strategy source metadata was captured.
What recovery means
Recovery is provenance, not magic. Tier 1 strategy source can usually be inspected, hash-checked, and optionally evaluated with trust = TRUE. Tier 2 strategies may depend on external functions or package state, so ledgr records the source text, hashes, parameters, dependency metadata, and warnings that explain what was captured and what remains outside the run artifact.
Plot The Promoted Evidence
A report should show the promoted run’s path, not only its scalar metrics. The equity table already contains the information needed for a compact equity and drawdown view.
promoted_equity <- ledgr_results(reopened, what = "equity") |>
  mutate(drawdown_axis = drawdown * equity[[1]] + equity[[1]])

ggplot2::ggplot(promoted_equity, ggplot2::aes(x = ts_utc)) +
  ggplot2::geom_line(
    ggplot2::aes(y = equity),
    linewidth = 0.8,
    color = "#1f77b4"
  ) +
  ggplot2::geom_area(
    ggplot2::aes(y = drawdown_axis),
    fill = "#d55e00",
    alpha = 0.20
  ) +
  ggplot2::labs(
    title = "Promoted candidate equity path",
    x = NULL,
    y = "Equity",
    caption = "Orange area scales drawdown onto the equity axis for compact review."
  ) +
  ggplot2::theme_minimal(base_size = 12)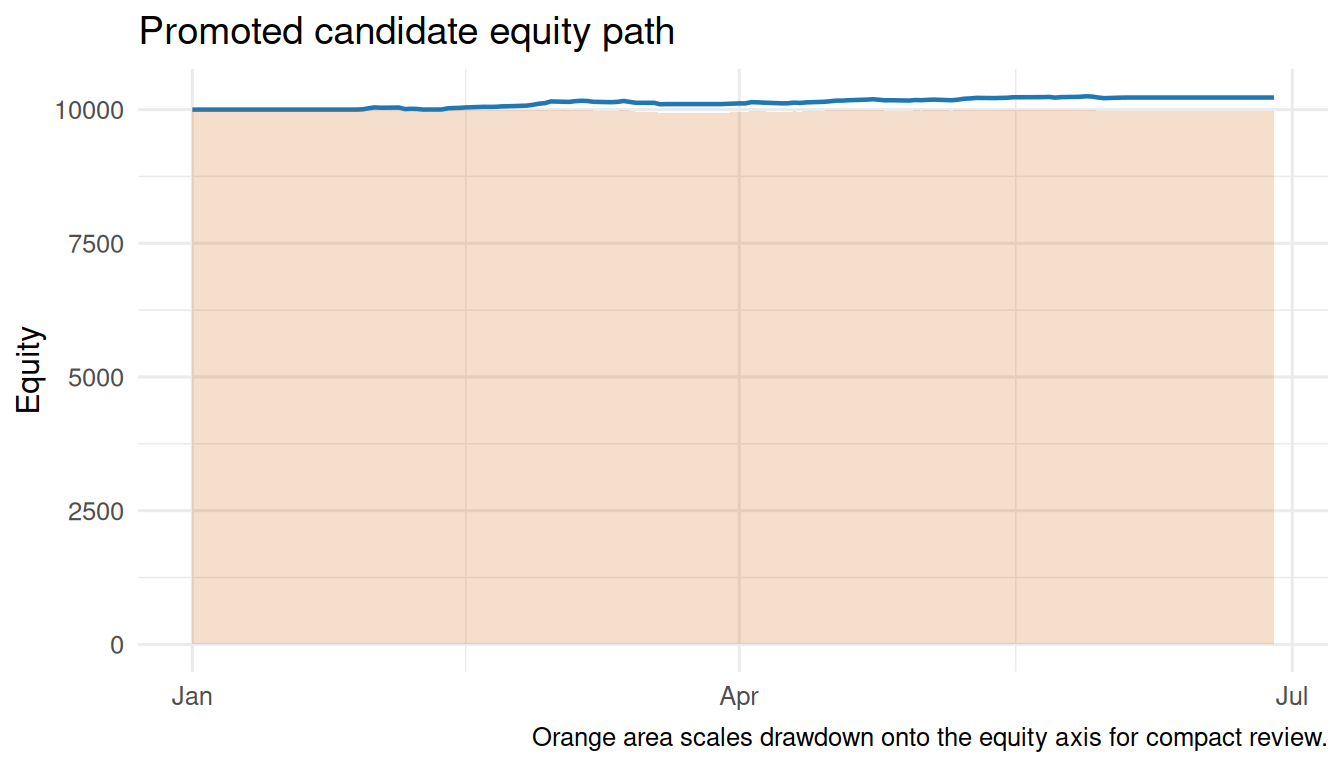
What Promotion Does Not Prove
You now have a promoted candidate. It means you can reopen the exact evidence trail: the sealed data, feature declarations, parameter values, run identity, candidate row, and promotion note. It does not mean the strategy will generalize.
A single-window sweep is exploratory evidence with an audit trail. Naive sweep-and-pick selection is a selection-bias risk because every candidate was compared on the same evidence window. Picking the highest metric from that window can overfit the sample even when every individual run was deterministic and leakage-safe at the pulse boundary. The more candidates you try, the more opportunity you create for sample-specific luck to look like skill.
%%{init: {"theme": "base", "flowchart": {"nodeSpacing": 18, "rankSpacing": 22, "curve": "linear"}, "themeVariables": {"fontFamily": "system-ui, -apple-system, Segoe UI, sans-serif", "fontSize": "15px", "primaryColor": "#f8fafc", "primaryTextColor": "#1f2937", "primaryBorderColor": "#64748b", "lineColor": "#64748b", "secondaryColor": "#eef2ff", "secondaryTextColor": "#1f2937", "secondaryBorderColor": "#64748b", "tertiaryColor": "#fff7ed", "tertiaryTextColor": "#1f2937", "tertiaryBorderColor": "#fb923c"}}}%%

flowchart TB
  window["Same evidence window<br/>Candidate 1<br/>Candidate 2<br/>Candidate 3<br/>Candidate ..."]
  pick["Pick highest metric"]
  caveat["Selection recorded<br/>not validated"]

  window --> pick --> caveat
If the question is whether the selection holds up beyond this sample rather than whether the artifacts reproduce, use vignette("selection-integrity", package = "ledgr") and vignette("walk-forward", package = "ledgr"). They weigh the selection; neither proves that it generalizes.
This is the same selection-bias boundary that separates reproducible sweep evidence from held-out evidence.
Try it
Write one sentence explaining why you promoted the candidate and one sentence explaining why that promotion is not validation. If the second sentence feels hard to write, the selection rule probably needs more work.
Cost Models Are Fixed Inputs
Cost models are part of the experiment identity. A sweep varies feature parameters and strategy parameters across the declared grid; it does not compose cost models as another grid dimension. If you want to compare different cost assumptions, run separate experiments or separate sweeps with explicit cost_model values and compare the resulting evidence.
A future ledgr_cost_grid() may make cost assumptions participate in candidate identity deliberately. That API has not shipped, so do not expect ledgr_grid_cross() to accept cost-model dimensions.
Explicit Non-Goals
Sweep mode intentionally leaves some decisions outside the API. It does not ship:
- automatic winner selection or
ledgr_tune(); - cost-grid composition such as
ledgr_cost_grid(); - paper/live trading adapters;
- intraday-specific support;
- full per-candidate committed-run artifacts.
Where Next
- For selection-bias diagnostics over a sweep, read
vignette("selection-integrity", package = "ledgr"). - For held-out evaluation of a selection rule, read
vignette("walk-forward", package = "ledgr"). - For feature maps, indicator identity, and active aliases, read
vignette("indicators", package = "ledgr"). - For durable run comparison after promotion, read
vignette("experiment-store", package = "ledgr").